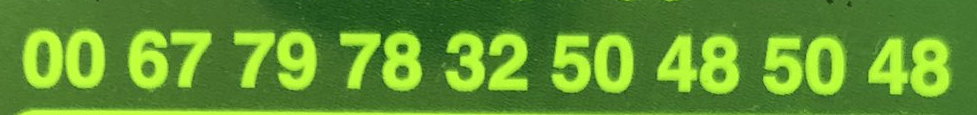
Measuring entropy is one of the activities that cryptographers use when designing random number generators. I always like the irony of a universe where there is an increasing amount of disorder, but when you want to make a source of random-ness, then it always seems to be infected with hidden layers of predictability. Random noise seems to be one of those nice ideas that is very difficult to obtain in practice, because there are a huge number of repetitive, predictable sources of information that drown out the random-ness. So random noise generation becomes a search for how to remove bias, or interference from non-random sources, followed by the refinement of statistical techniques to show how successful the removal has been.
As I have noted before, the better the encoding and encryption technique used, the more the resulting output looks like random noise. My 'think about things from a different viewpoint' brain takes that and inverts it, arriving at the conclusion that truly random noise must contain hidden information - but we just don't know the key (or the coding scheme!) and so can't decode it. I'm sure there is lots of money to be made from this type of thing, and, of course, there is!
Hackers also use entropy, but often for different reasons. If cryptographers have put lots of effort into making encryption produce noise-like data, then one way to look for encrypted data is to look for randomness. Firmware is a good place to look, because it is usually an intrinsic part of the underlying platform that services are built on, and so is an appealing target. So hackers look at firmware in a number of ways, which I always think of as different 'filters'...

The first filter that most people use is my old favourite: ASCII characters and strings. Open the extracted firmware (or data file containing it!) in a hex editor, and look for readable characters - for some reason, hex editors always seem to have a strict ordering of columns: index on the left, then the data in hex, and then the same data in ASCII printable characters. In the old 8-bit days, then you could expect to see lots of strings containing everything that appeared on the screen as text, plus lots of things that the programmer probably didn't want you to ever see: debug messages, passwords or cheat codes for reviewers/managers, initialisation settings, and more. As time has gone on, there is less and less useful information to be found, but sometimes... Wherever valuables are hidden, then there are people who will make tools to help the search. So truffleHog is just one example of a utility that searches for interesting strings on GitHub, and there are lots of other 'Information Gathering' and 'Reconnaissance' tools that will attempt to locate strings. The example screenshot above shows HexFiend, a hex editor for MacOS, looking at itself...
What I look for in a hex editor, of course, is the ability to add offsets, to rotate, to invert and to do other 'ASCII-obscuring'-related processes in order to try and locate obfuscated strings...

Another filter that is used relates to randomness. Utilities like binwalk provide a graph that shows Entropy on the vertical axis, and index (position within the file) on the horizontal axis (binwalk does lots of other things too!). The binwalk example file shows exactly the sort of graph that the hacker probably isn't looking for: on the left, a short block with low entropy, followed by a big block with an entropy of about 0.6, followed by another short block with low entropy, then a block of about 0.5... and finally, a long block with low entropy. Nowhere in this graph is a flat block up at the 1.0 level, which would usually be inferred to mean either encrypted data, or better, keys!
(As often happens, one thing leads to another, so this thinking about binwalk took me in a very different direction, which will feature in a future blog post...)
The problem with just typing >binwalk -E filename.bin and then looking at the graph is that people get told that a flat line at 1.0 means encrypted or key data (with a short flat spike probably indicating keys!), a rough line peaking at 1.0 but with little spikes down to 0.9 or so means compressed, flat areas with zero entropy are just fixed data, and anything else is code. There's a problem here, and it relates to knowing what entropy is.
Remember that entropy is a measure of disorder. So when it is up at 1.0, it means that each successive value is very different to the previous one, and so on. - random values! Conversely, down at 0, it means that each successive value is no different to the previous one, etc. Note that 'no different' does not mean: '00 00 00 00 00...', it means lots of repeated values. So the graph doesn't show the values, it shows the variability instead.
With all of this in mind, we can now think about hiding data. If I was trying to hide keys or encrypted code inside firmware, knowing that people would use binwalk to find those keys, then all I need to do is to change the variability of the keys or encrypted code. One simple way to do this is to just add zero bytes (or any other value) every n bytes. If we add 00 every other byte then we have an entropy of zero for the 00 bytes, and 1 for the keys or code, giving an overall entropy of 0.5. We have doubled the size of the data, but for keys this does not matter, and extracting the keys is trivial! However, if you look at the obscured key data in a hex editor, then all of those 00 bytes will be obvious...
Alternatively, you could split the keys or code into nibbles: half bytes. So 7E would become 70 and 0E. If I do this to lots of data, then there are only 32 different values: 0-F followed by 0, or 0 followed by 0-F. The entropy is now not anywhere near 1.0 any longer, because all those zeroes reduce the variability - you can predict that there will be a zero either at the start or the end of the two character hex digit. But the data isn't fixed either (it isn't just 7E 7E 7E 7E 7E...), and so the entropy is about 0.5. Not only that, but looking at the data in a hex editor, it is going to be much harder to spot the zeroes. The cost of this better obfuscation is that the extraction of the keys is slightly harder... So now the key data isn't going to be obvious in either binwalk or a hex editor. In other words, you can 'design' the entropy of your data if you know what is being measured.
When I wrote this, it didn't seem that special. But now, when I go back to it, the idea that you can edit your data so that you control the entropy is very interesting indeed! It kind of takes back some of the power that randomness takes away from you...
---
Many articles these days use clickbait techniques to get your click, and then break that trust by never actually answering any of the questions they pose. So, let's prevent this right here and now:
Entropy - what is it?
The second sentence (I've never recovered fully from the Amazon review of my book where someone counted the number of pages before I actually said what something did...) tries to describe entropy without being a definition: 'a measure of the disorderliness...' . But two sentences later, my favourite is the 'un-bake a cake' metaphor. Maybe I should have said: You can't un-write a blog post...'!
Entropy - what does it mean?
This is the real fascinating thing about entropy: the more efficient you encode or encrypt something, the higher the entropy, and the more it stands out and waves a flag saying: 'Here I am!'. And the mitigation that I suggest is to reduce that efficiency by making it bigger! I suppose that having it secure and hard to find is a good compromise, but I'm now wondering if there is a way of reducing the entropy algorithmically that is hard to detect - and ultimately, the optimum way of doing that would probably also look something like noise - but special noise that has the effect of reducing the entropy of the actual data than looks like noise because it is efficiently encrypted or encoded. Unfortunately, I'm not a good enough cryptographer to to able to figure out if this can be done, but I'm always open to feedback!
Entropy - why is it useful?
The third paragraph is my 'reverse way of looking at the way the world works' moment: You can use entropy as a measure of how good your encoding or encryption is. I've always loved the way that this is the opposite of sayings like 'the perfect shape is a circle...'. Playing double jeopardy then, it follows that the more ordered a system is, the worse the encoding or encryption. In this case, the universe contains a lot of very badly encoded and encrypted information, and I am very, so very glad that we don't have the keys or the algorithms!
---
If you find my writing helpful, informative or entertaining, then please consider visiting the following link for my Synthesizerwriter alias (I write several blogs, but it makes sense to only have one 'Coffee' donation link!):