Friday, 15 May 2020

The considered view is better than the initial reaction...

Some time ago, when lockdown first started, there was a lot of mainstream media coverage about how insecure some videoconferencing apps were. As always happens these days, some security companies may have been tempted to use this as a way to get publicity by releasing reports detailing their investigation into the risks of using those videoconferencing apps, plus some videoconferencing marketing people might have considered using this as an opportunity to promote their product, and all of this was then reported by mainstream media with a variety of biases and hidden agendas, plus the ongoing desire to capture eyeballs and clicks. I've been intrigued for a while by the view that says that 'Fake News' is a new phenomenon, because I have always thought of all news 'information' as being potentially flawed and requiring a critical appraisal. More broadly, the:

'Trust no source, check everything'

approach has always been very useful insurance. One example that I'm familiar with is that some editions of some of the standard text-books on analogue filter design have contained errors in some of the formulas (or formulae). The tricky bit here is 'some', because this means that the usual 

'check in a couple of reference works' 

approach can fail, because they might both contain the same error! Also, in an online world, what counts as a 'reference work' these days? I have always been intrigued by the way that YouTube and other online social media platforms use words like 'authoritative' when describing sources of information - they don't use words like 'legal' or 'experts' or 'scientists' or 'legislators'. Now appearing to be 'authoritative' would seem to be rather subjective to me, whereas acquiring 'expert' status can be objectively assessed, albeit with caveats because the assessment can be flawed. 'Edition n contains errors, whilst edition n+1 fixes previous errors, but may still contain a different set of errors' is one way of looking at it.

When the mainstream media report on security, then there is a spectrum of opinions from security practitioners about how well they do it, ranging from 'They don't understand', through 'Most of this is kind of true, but...' to 'They understand'. My usual reaction is something like: 'They are describing some of the basic levels of this, but many of the important nuances and fine detail are missing, because to simplify a complex subject for a general audience is obviously a challenge.'

On Twitter I said that my first source of news was from inside the security community, and that Bruce Schneier or Brian Krebs (or Matthew Green, but I kept the Tweet short) would be my preferred way to get an initial informed view on any security issue that the mainstream media were talking about. And yes, I'm well aware that it is rare for the mainstream media to talk about security, and that the time delays in publishing specialised blogs and mainstream news are different. And no, the order wasn't meant to be significant!

So here we are some time after lockdown started, and this is probably a good time to look and see what the 'considered' opinions are.

Here's Bruce Schneier giving some thoughts, which refers to an NSA survey and another one from Mozilla, plus another from Matthew Green, and some on a specific app from Brian Krebs ... Many security companies and organisations have published guides on 'Things to Consider' when using a videoconferencing app or 'working at home'. - here are some examples from Kaspersky , ITGovernance , the New Zealand NCSC , and a the UK NCSC  ...

It is very interesting to take the surveys and to compare them to a lot of the mainstream media headlines, articles and some social media 'statements' that appeared in the first days of the lockdown. What you find is, and I'm repeating this deliberately: 'They are describing some of the basic levels of this, but many of the important nuances and fine detail are missing, because to simplify a complex subject for a general audience is obviously a challenge.' For me, it is interesting to see how many of the statements like  'X does end-to-end encryption (or choose your own feature of interest), Y does not.' are not backed up by the surveys - either as 'X and Y do not', or more interestingly and relevantly: 'it isn't as simple as that...'.

So is the considered view better than the initial reaction? I would guardedly say: 'Yes', but that's not a complete and definitive 'yes'. It depends...and that opens up a whole series of interesting things to explore about truth...

---

If you find my writing helpful, informative or entertaining, then please consider visiting the following  link for my Synthesizerwriter alias (I write several blogs, but it makes sense to only have one 'Coffee' donation link!):




Wednesday, 6 May 2020

One day there's going to be an automated security disclosure...

I was just a little surprised when Instagram sent me a message that appeared to 'express an opinion'...


But it set me thinking about how easy it would be for a developer to write an automated message template that leaks confidential information via an unexpected side-channel... Risk assessment of tiny scripts that do apparently innocuous things, anyone?

Names are interesting things. I once tried to get a hi-tech music themed sticker printed by one of the on-line drop-shipping companies and the artwork was rejected because of a copyright strike. I had used the word: 'Device', as in an electronic music device, but this was flagged up because 'Device' was the name of an American industrial metal band in 2012, and so was trademarked...

---

If you find my writing helpful, informative or entertaining, then please consider visiting the following  link for my Synthesizerwriter alias (I write several blogs, but it makes sense to only have one 'Coffee' donation link!):


Monday, 4 May 2020

Hardware.IO - my tiny bit of a major Virtual Conference! aka 'What are Wall Challenges'?

I was busy during April 2020. Several deadlines all conspired to converge on the same 'month end' delivery date. But one of them was the sort of project that I really like: puzzles!

Antriksh at Hardware.IO asked me if I could reprise the 'Wall Challenges' that I did for the 2017 and 2018 Hardwear.IO conferences in Den Haag (The Hague) in The Netherlands. '21 mysterious A4 pages blu-tacked to the walls with only a brief explanation' is something I've been doing for various events for some time, and it is a low-key, often mostly overlooked facet of the whole event - except for the people who get into it. If you go to one of the big, serious, 'suits' events, then you find teams of people who turn up just for the 'Capture the Flag' penetration or 'Capture the Signal' radio competitions etc., and they are usually pretty totally focussed on that for the whole event.

My 'Wall Challenges' are several opposites at the same time: they are carefully crafted training exercises, just like a 'Capture the Flag' contest; but they are also deliberately abstracted, which isn't a CTF or CTS feature. They are also fun challenges! So I thought that this might be a good time to look at what they are for, and why you might like to consider immersing yourself in one next time you see a sheet of paper stuck on the wall...(physical or virtual!).

Wall Challenges - what are they?

If you've ever wondered how people acquire an assured, casual ease with some technical subjects: 'facility' is one of the words that sometimes gets used, then one way to do it is not to read lots, or watch videos or attend lectures/seminars. Instead, actually doing something is often another good way to build familiarity, explore the limits of what you know (or don't know), and maybe extend your boundaries a bit. This is your cue: keep reading and do some WallChallenges!

Wall Challenges are apparently simple problems that are often harder than they appear, and doing them is good for you! If you ever wanted a Sudoku that was more than just a few numbers in squares, or that required programming to solve, or that went into the mathematics or theory a bit more, then you might find that Wall Challenges are exactly what you are looking for.

What sort of topics are covered? Things like Binary, Hex, Number bases, ASCII, ROT-13, Hashes, Look-up tables, Modulo arithmetic, Pointers, Pictograms, Anagrams, Cryptic clues, Codes, the Periodic Table, Lateral thinking, Critical thinking, and more. Solving them can often be done with just pen and paper, although some require a spreadsheet, and the harder ones can require some programming (Python is what I've used...). In the course of finding solutions, you will also acquire a collection of interesting look-up tables (ASCII, Periodic Table...) that often have interesting histories and are very good things to know for Pub Quizzes or Only Connect (My Team didn't get onto TV, by the way...).

There's a school of thought that making things simple is both a work of genius and a genius-level way of making it look trivial. When Einstein wrote 'E=mc squared' then it looked simple enough, but the ramifications were universe-altering. Now, Wall Challenges aren't quite at that level, but they can change the way that you think...and that's the whole point. These aren't trivial ways to pass time, they are intended to make you think about things that might well be useful in Penetration Testing, Risk Assessments, Threat Modelling, Security Analysis, White and Black-hat Hacking, and so on and so on.

I'm going to show examples, and in each and every case, the answer will be 'Cryptography', and it will be in capitals, which is supposedly how 'real' cryptographers do writing (sometimes). Not the crypto of block-chain currencies, but the 'hidden writing' of encryption, AES, CIA and several other three-letter acronyms (that's Confidentiality, Integrity and Availability), of course...). The Wall Challenges shown here are deliberately simple and easy to solve, plus you already know the answer! Real Wall Challenges are a bit harder, and some, like the ones you find at hardware security conferences like Hardwear.io, are very hard indeed.

Anyway,  here's the first Wall Challenge, which is called 'Bounce':

YCHRPYAPRTGO

Okay, so even though I've given you the answer, you are probably struggling to see how we went from cryptography to that! What you need are some strategies to get you started, and the first of these is:

Strategy 1: Start at the ends and scan across, skipping to see if anything looks interesting.

Well, the first letter is 'Y', reading from left-to-right, and 'Y' is the last letter of CRYPTOGRAPHY, but continuing gives 'YCHRPY' which isn't CRYPTOGRAPHY backwards (which is YHPARGOTPYRC, of course). The other end is 'O', and going right-to-left across gives 'OGTRPA' which isn't helping much either. 

So let's repeat that, but skipping every other letter, and we get 'YHPARG' and 'OTPYRC'. Woah! That's CRYPTOGRAPHY backwards isn't it? So if we start at the C, second letter in from the left, and miss out every other letter, then we get 'CRYPTO' as we go across from left-to-right, and then we need to reverse direction and go right-to-left to get 'GRAPHY'. So at the end of the word, we 'bounce' and reverse direction. Maybe there should be a brick wall graphic on the piece of paper on the right hand-side? 

So, we now know that doing a bit of adjusting of the order of letters can hide a word, but what use is that? Well, one of the basic transformations that encryption algorithms like AES use is shuffling the order of the data bytes...

Here's the second Wall Challenge, which is called 'Inside out':

PARG
HRCO
YYPT

Starting at the 'P' on the left and going across to the right doesn't give anything useful (PARG might be the start of PARGETER, but it is an unusual word, and there aren't any 'E's!), so try right-to-left from the 'G' - which gives 'GRAP' and we know that is in the middle of the word we are looking for... But in a real challenge then we would not know what the hidden word is, and so this wouldn't be that useful. 

What we probably need is a revised strategy:

Strategy 1: Start at the ends and scan across, vertically and diagonally, skipping to see if anything looks interesting.

If we do this from the lower left hand 'Y', then we get 'YHP', and if we turn the corner at the 'P' to go across to the right, then we get 'YHPARG', which is the end half of CRYPTOGRAPHY, but reversed. If we carry on going round then we eventually hit the 'Y' where we started, so let's turn and carry on in a spiral, which takes us all the way to the 'C', giving 'YHPARGOTPYRC', which is CRYPTOGRAPHY backwards again. So this time, the word was written 'inside out', as a spiral from the initial letter 'C'. Here's me trying to make it more obvious by using coloured letters for the first three letters in the spiral:

PARG
HRCO
YYPT

...and then the last letters...

PARG
HRCO

YYPT

What have we learned this time? Well, it seems that people who are used to reading from left-to-right can find it difficult to go from right-to-left, and that turning things into a 4x3 grid and using a spiral is hard to read. So the shuffling that encryption algorithms carry out looks like it can be effective at obfuscating (a fancy way of saying 'concealing') the sequence of letters in a word. Now, I'm not aware of any cryptographic algorithms that use spirals - they tend to just shuffle or rotate rows or columns. But spirals occur all over the place in nature, and people like them, so there may well be a bias in my usage of them.

The third challenge changes tack, and goes for numbers instead of letters, and is called 'Index':

3 18 25 16 20 15 7 18 1 16 8 25

Whenever numbers appear in a Wall Challenge, then you use another strategy:

Strategy 2: Are the numbers in decimal, hex or another base?

In this case, the numbers appear to be decimal. Often the '3' will be shown as '03' to make you think that it might be in hexadecimal or some other base. Notations like 0x8E for indicating hexadecimal numbers are quite rightly used in programming to make it unambiguously perfectly clear that the '8E' is in hex, but in Wall Challenges there are no rules, and so clues like '0x' are rare. In fact, if I did use that notation, then it would probably be mis-direction!

Oh, nearly forgot:

Strategy 0: There are no rules, standard practices or conventions. (The bad guys break them all the time anyway.)

So we have a list of numbers which might be decimal, so what do we do next? A variation of Strategy 1 is a good starting point: look at the ends, and then scan across and find the largest and smallest numbers. In this case, 3 and 25 are the ends, 1 is the smallest value, and 25 is the largest value. This information is full of clues - can you think of something that comes in a set with about 25 different members?

How about the alphabet? 26 letters... So starting on the left, what is the 3rd letter of the alphabet? 'C'. The 18th? Er, and here you get to the first lookup table. Open your favourite spreadsheet of choice and create a table that has the numbers from 1 to 26 in the first column, and then the letters from A-Z in the second column. Voila - you now have a useful Wall Challenge solving aid, and the beginnings of a collection of tables about symbols and numbers that you will be using a lot. Here's what I produced:


Producing lookup tables like this also has a strategy:

Strategy 3: Whenever you need a look-up table, make one, save it, and add a few extra columns so you are better prepared for next time...

For this table, I added the third column, which is a reversed index to the alphabet. This is good preparation for what myself and lots of other security analysts call 'The T-Shirt Effect'. We all wish that we had a T-Shirt that says on it: 'There's no way that would ever happen!', because this occurs  every time in a Risk Assessment or Threat Modelling session - there's always someone who says these words. In fact, governments around the world probably heard the same or similar words when they looked at the risk of a problem with a new virus epidemic at any time in the last decade...

Anyway, the table makes looking up the 18th letter of the alphabet much easier: 'R'. Going across from left to right, converting from the index number to the corresponding letter of the alphabet, we get: 'CRYPTOGRAPHY' just like you knew we would.

The fourth introductory Wall Challenge is a bit different, and is called 'Standard Interchange':

67 82 89 80 84 79
71 82 65 80 72 89

This time, the ends are bigger than the previous example, at which point experienced Wall Challenge solvers use another strategy:

Strategy 4: Is the range of numbers 26, 36, or some other small number that might contain an alphabet and numbers?

The lowest is 65, and the highest is 89 which is a range of 24, so immediately you should be suspecting something based on the alphabet. Now 65 is one of those 'magic' numbers that shouts out for attention, because the capital letter A is 65 in ASCII, the 'American Standard Code for Information Interchange'. 89 is Y, and so it looks like this is the time to get or make an ASCII lookup table for your collection.

If you replace 67 with the ASCII letter equivalent, you get 'C'. 82 is R, 89 is Y, and before you know it, you have: 'CRYPTOGRAPHY'.

There's an interesting thing to note here. The index table for the alphabet is actually a sub-set of part of the ASCII table - if you add 64 to the first column then it decodes CYRPTOGRAPHY perfectly fine, and this could be added as a fourth 'Shifted ASCII column'... But the ASCII table has lots of other characters in it - numbers, lowercase letters and all sorts of symbols, plus characters that control what a printer does (line feed, carriage return and those curious references back to mechanical printers that borrowed terminology and actions from mechanical typewriters...), as well as characters that don't actually print anything. If you go beyond the 127th character, then ASCII changes from something which is pretty consistent everywhere, to something with lots of alternatives. This 'Extended ASCII' is still standard, it's just that there are lots of standards covering all the variations.

So a nefarious puzzle-setter who wanted to hide some text might well make the capital A have the value 65, but that doesn't mean that it is automatically ASCII. Suppose B was 64, and C was 63? The correct reaction at this point is to already have your spreadsheet open and be adding a column, by the way...

That completes this first introduction to Wall Challenges. If you want more examples, then there are a few posts in this blog that contain them, and attending a Hardwear.io or Nullcon conference might get you a view before anyone else...

Resources

My YouTube channel. Go to the 'Playlists' and look for 'Wall Games'. There are quite a few other videos here to look at, covering topics like security, anime and music...

Hardwear.IO Virtual Con 2020 Questions Only - this is the 'Questions Only' version of the Wall Challenges from the Hardwear.IO Virtual Conference 2020 held online on the 30th of April and 1st of May 2020.

Hardwear.IO Virtual Con 2020 Questions and Answers

Hardwear.IO 2018 Questions

Hardwear.IO 2018 Questions and Answers

Hardwear.IO 2017 Questions

Hardwear.IO 2017 Questions and Answers

Hardwear.IO are excellent hardware security conferences! 

Nullcon is a recommended security conference...

The Nullcon 2020 Badge meta-puzzle...

---

If you find my writing helpful, informative or entertaining, then please consider visiting the following  link for my Synthesizerwriter alias (I write several blogs, but it makes sense to only have one 'Coffee' donation link!):


Saturday, 2 May 2020

Entropy - what is it, what does it mean and why is it useful?

Entropy is fascinating. It is a measure of the disorderliness of a system - and so, not unsurprisingly, it has a tendency to increase. You can't un-bake a cake, as they say. Organising, sorting and tidying are all counter-measures, but like recycling, it turns out that the real universe is more complex and tricky to work with than you might hope, and so trying to do 'the right thing' often has the opposite effect.

Measuring entropy is one of the activities that cryptographers use when designing random number generators. I always like the irony of a universe where there is an increasing amount of disorder, but when you want to make a source of random-ness, then it always seems to be infected with hidden layers of predictability. Random noise seems to be one of those nice ideas that is very difficult to obtain in practice, because there are a huge number of repetitive, predictable sources of information that drown out the random-ness. So random noise generation becomes a search for how to remove bias, or interference from non-random sources, followed by the refinement of statistical techniques to show how successful the removal has been.

As I have noted before, the better the encoding and encryption technique used, the more the resulting output looks like random noise. My 'think about things from a different viewpoint' brain takes that and inverts it, arriving at the conclusion that truly random noise must contain hidden information - but we just don't know the key (or the coding scheme!) and so can't decode it. I'm sure there is lots of money to be made from this type of thing, and, of course, there is!

Hackers also use entropy, but often for different reasons. If cryptographers have put lots of effort into making encryption produce noise-like data, then one way to look for encrypted data is to look for randomness. Firmware is a good place to look, because it is usually an intrinsic part of the underlying platform that services are built on, and so is an appealing target. So hackers look at firmware in a number of ways, which I always think of as different 'filters'...


The first filter that most people use is my old favourite: ASCII characters and strings. Open the extracted firmware (or data file containing it!) in a hex editor, and look for readable characters - for some reason, hex editors always seem to have a strict ordering of columns: index on the left, then the data in hex, and then the same data in ASCII printable characters. In the old 8-bit days, then you could expect to see lots of strings containing everything that appeared on the screen as text, plus lots of things that the programmer probably didn't want you to ever see: debug messages, passwords or cheat codes for reviewers/managers, initialisation settings, and more. As time has gone on, there is less and less useful information to be found, but sometimes... Wherever valuables are hidden, then there are people who will make tools to help the search. So truffleHog is just one example of a utility that searches for interesting strings on GitHub, and there are lots of other 'Information Gathering' and 'Reconnaissance' tools that will attempt to locate strings. The example screenshot above shows HexFiend,  a hex editor for MacOS, looking at itself...

What I look for in a hex editor, of course, is the ability to add offsets, to rotate, to invert and to do other 'ASCII-obscuring'-related processes in order to try and locate obfuscated strings...

Another filter that is used relates to randomness. Utilities like binwalk provide a graph that shows Entropy on the vertical axis, and index (position within the file) on the horizontal axis (binwalk does lots of other things too!). The binwalk example file shows exactly the sort of graph that the hacker probably isn't looking for: on the left, a short block with low entropy, followed by a big block with an entropy of about 0.6, followed by another short block with low entropy, then a block of about 0.5... and finally, a long block with low entropy. Nowhere in this graph is a flat block up at the 1.0 level, which would usually be inferred to mean either encrypted data, or better, keys!

(As often happens, one thing leads to another, so this thinking about binwalk took me in a very different direction, which will feature in a future blog post...)

The problem with just typing >binwalk -E filename.bin and then looking at the graph is that people get told that a flat line at 1.0 means encrypted or key data (with a short flat spike probably indicating keys!), a rough line peaking at 1.0 but with little spikes down to 0.9 or so means compressed, flat areas with zero entropy are just fixed data, and anything else is code. There's a problem here, and it relates to knowing what entropy is.

Remember that entropy is a measure of disorder. So when it is up at 1.0, it means that each successive value is very different to the previous one, and so on. - random values! Conversely, down at 0, it means that each successive value is no different to the previous one, etc. Note that 'no different' does not mean: '00 00 00 00 00...', it means lots of repeated values. So the graph doesn't show the values, it shows the variability instead.

With all of this in mind, we can now think about hiding data. If I was trying to hide keys or encrypted code inside firmware, knowing that people would use binwalk to find those keys, then all I need to do is to change the variability of the keys or encrypted code. One simple way to do this is to just add zero bytes (or any other value) every n bytes. If we add 00 every other byte then we have an entropy of zero for the 00 bytes, and 1 for the keys or code, giving an overall entropy of 0.5. We have doubled the size of the data, but for keys this does not matter, and extracting the keys is trivial! However, if you look at the obscured key data in a hex editor, then all of those 00 bytes will be obvious...

Alternatively, you could split the keys or code into nibbles: half bytes. So 7E would become 70 and 0E. If I do this to lots of data, then there are only 32 different values: 0-F followed by 0, or 0 followed by 0-F. The entropy is now not anywhere near 1.0 any longer, because all those zeroes reduce the variability - you can predict that there will be a zero either at the start or the end of the two character hex digit. But the data isn't fixed either (it isn't just 7E 7E 7E 7E 7E...), and so the entropy is about 0.5. Not only that, but looking at the data in a hex editor, it is going to be much harder to spot the zeroes. The cost of this better obfuscation is that the extraction of the keys is slightly harder... So now the key data isn't going to be obvious in either binwalk or a hex editor. In other words, you can 'design' the entropy of your data if you know what is being measured.

When I wrote this, it didn't seem that special. But now, when I go back to it, the idea that you can edit your data so that you control the entropy is very interesting indeed! It kind of takes back some of the power that randomness takes away from you...

---

Many articles these days use clickbait techniques to get your click, and then break that trust by never actually answering any of the questions they pose. So, let's prevent this right here and now:

Entropy - what is it?

The second sentence (I've never recovered fully from the Amazon review of my book where someone counted the number of pages before I actually said what something did...) tries to describe entropy without being a definition: 'a measure of the disorderliness...' . But two sentences later, my favourite is the 'un-bake a cake' metaphor. Maybe I should have said: You can't un-write a blog post...'!

Entropy - what does it mean?

This is the real fascinating thing about entropy: the more efficient you encode or encrypt something, the higher the entropy, and the more it stands out and waves a flag saying: 'Here I am!'. And the mitigation that I suggest is to reduce that efficiency by making it bigger! I suppose that having it secure and hard to find is a good compromise, but I'm now wondering if there is a way of reducing the entropy algorithmically that is hard to detect - and ultimately, the optimum way of doing that would probably also look something like noise - but special noise that has the effect of reducing the entropy of the actual data than looks like noise because it is efficiently encrypted or encoded. Unfortunately, I'm not a good enough cryptographer to to able to figure out if this can be done, but I'm always open to feedback!

Entropy - why is it useful?

The third paragraph is my 'reverse way of looking at the way the world works' moment: You can use entropy as a measure of how good your encoding or encryption is. I've always loved the way that this is the opposite of sayings like 'the perfect shape is a circle...'. Playing double jeopardy then, it follows that the more ordered a system is, the worse the encoding or encryption. In this case, the universe contains a lot of very badly encoded and encrypted information, and I am very, so very glad that we don't have the keys or the algorithms!

---

If you find my writing helpful, informative or entertaining, then please consider visiting the following  link for my Synthesizerwriter alias (I write several blogs, but it makes sense to only have one 'Coffee' donation link!):


Thursday, 19 March 2020

Puzzles and security - a synergistic relationship?

Apparently, human beings are hard-wired to detect patterns. Sometimes this is good, but sometimes it can be too effective, or misleading, or subject-to-multiple-interpretations... A cynic might rewrite it as:

Humans are hard-wired to detect patterns, even when the patterns aren't there...

Patterns are very important in security, or, to put it another way: the hiding of patterns is often very important in security. Encryption is a good example of a way of hiding the patterns of ASCII-encoded text data and making them look slightly more noise-like. 'Obfuscation' is that wonderful word for hiding something in plain sight. I always remember something that was drilled into me when I worked on audio encoding:

The better the coding scheme, the more the output looks like noise.

And this hooks very nicely into the way that people use entropy as a way to find encoded data - plain program code has low entropy, but encrypted passwords (or other important/valuable data) have high entropy. So scanning code for high entropy sections would seem to be a good way of finding interesting encrypted data...

Unfortunately, one of the obvious things to do when you start to protect data with encryption is to hide it in similar data. Encryption is not the only way to increase the entropy of program code, of course, just applying a simple compression scheme would also work. This 'one action leads to a corresponding follow-up action, which then leads to another action...' is the 'climbing a ladder' escalation analogy that can be used to model all sorts of interchanges. 

Puzzles are interesting because they can train you to look at problems in many different ways, and breaking assumptions - one of the other things that humans are very good at is making assumptions, of course. 

So, let's look at one of the puzzles on the Nullcon 2020 badge (and the answers), and see how it encourages potential puzzle solvers (like security analysts and cryptographers) to think laterally.

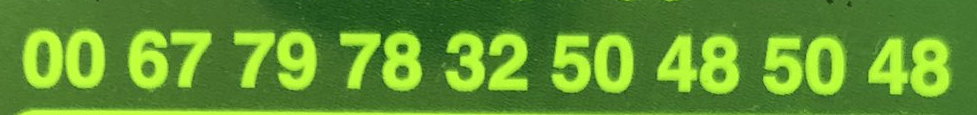
Here's what part of the top of the badge looks like:


 (There's something about the look of 'fluorescent green plastic' that makes it appear super-cool!)

Puzzle setters like myself know that there are clues that give away typical encodings that are used for text, so any numbers between 46 and 122 (decimal) would tend to suggest an ASCII encoding (A-z, plus 0-9 plus '.' and '/'), which would be confirmed by having lots of '32's indicating spaces. In this case, the initial number is '00', which is deliberate misdirection, and is based on people initially looking at the beginning and ending of sequences - putting the 32 mid-sequence kind of hides it amongst the other numbers.

So the '00' is hopefully going to cause some people to immediately reject this as being ASCII-encoded text, but then if they look closer, they will see the '32' and note that all the other numbers are between 48 and 122... Which means that it probably is ASCII-encoded text, but that the first character is different or special in some way. One thought at this point might be that this is an index: the first piece of encoded text might be preceded by a zero, and so other encoded text would then be examined to see if the initial numbers were 01, 02 03, etc. But the other number puzzles on the badge do not follow this sequence (so one obfuscation method that a puzzle setter could potentially use would be to deliberately offset ASCII-encoded text so that the first number is an ascending index or offset...) and so there must be something else about the number '00'. Looking it up on an ASCII table quickly reveals the secret: 00 is the decimal number that represents the archaic non-printing 'NULL' character, and given the name of the conference for this badge (Nullcon!), it is obvious that the Null character is being used to replace four ASCII numbers with a single shortcut number!

One can imagine a puzzle setter who exploits this to encode other words with appropriately similar  extensions using the ASCII characters outside of the ./A-z, 0-9 (46-122) range. If the fictional conference called 'DevCan' wanted a badge, then this could be encoded with 127 (character for 'DEL' (delete)), then 08 ('backspace'), then 11 ('VT', the 08 ('backspace'), then 24 (character for 'CAN' (cancel)). Thus giving 127 08 11 08 24 for encoding DevCan. That 127 is a dead giveaway, so I suspect that the hex versions would be used instead: 7F 08 0B 08 18.

For Hex-encoded ASCII, then the numbers that people look for are 2E to 7B (./0-9A-z), so those two 08s and the 18 are good misdirection!

If the puzzle solver approaches things from the opposite end of the sequence (often a good technique to try), then the last four numbers are all inside the 0-9 range of 48-57 (decimal), and so are obviously numbers. Decoding them to '2020' is another strong clue that this is ASCII-encoded text.

Finally, there's the 32, which is like a waving red flag to anyone who is looking for ASCII-encoded text! One approach that a puzzler might take would be to replace this with another character: 00 (Null) being one candidate. But in this case, 00 is already used, so another character would be used. Using 00 (Null) as a replacement character for 'Space' might be something that a specific puzzle setter has used previously, of course, and so knowing who set the puzzle might be useful. Conversely, puzzle setters might strive to avoid using the same obfuscation methods more than once.

One difference between a puzzle and real world decoding is that puzzle setters like to give clues. The 32 in the middle of this sequence is one example, but for a conference called Nullcon, with a badge that has the word 'Nullconium' as well as 'Nullcon' written in a weird 'falling-over' books font, then there are lots of pointers to 'Nullcon' being a likely candidate for some encoded text on the badge - especially given the 'Periodic Table tile' / 'Top Trumps card' metaphor of the badge design.

If you have read this far, then you should now have had a glimpse of how puzzles like the Nullcon badge can encourage you to take an oblique look at problems, and thus may help you to solve your next challenge in an inventive and unusual way. And the world definitely needs novel solutions!

---

If you find my writing helpful, informative or entertaining, then please consider visiting the following  link for my Synthesizerwriter alias (I write several blogs, but it makes sense to only have one 'Coffee' donation link!):


Friday, 13 March 2020

Nullcon 2020 Conference Badge Answers

The Nullcon Goa 2020 Conference Badge is a meta-puzzle. There is lots of data all over it, and it obviously has some meaning, but it isn't the usual 'little bit of manufacturer metadata in the corner' stuff, or even a Verhoeff checksum. At a security conference, then there is almost no need to have any further instructions - the badge is intrinsically a challenge to people whose modus operandi is to question everything.

Of course, it might all mean nothing. Unless someone published the answers. If you don't want to know what all that data means, then stop reading now and click away ( Try this as a distraction! ). If you carry on reading, then welcome down the rabbit hole!

The badge was laser etched onto clear plastic (Now this is tricky - I'm not sure if that gorgeous green/orange plastic is 'clear' or 'transparent' - language is an impressively imprecise communication medium!) The design was produced as a DXF file, and has two slots for the lanyard, plus three other holes/circles (manufacturing detail!) There are more than twenty interconnected puzzles (hence the word: meta-puzzle) on the badge, and it looks very cool!  

(In the graphics that follow, I have deliberately left room around the central area so that when you print out this blog, there is plenty of room for notes and calculations...)

The first thing that you probably notice is the central 'tile', which looks like an entry in an alternative Periodic Table - or maybe one from a different universe (paywall) in the multiverse (not paywalled), where the elements are slightly different... A Google search for Nullconium doesn't reveal much, and assuming that it is a Latin word is satisfyingly self-referential. 'Nu' isn't an abbreviation for any element, either. ( Link to useful list for puzzle designers )  Atomic numbers as high as 2000 are way beyond current physics, and 2000+ fails as an atomic number because it isn't unique. The mass number of 20.167 is all wrong as well - it should be larger than the atomic number! At this point, it should be clear that this isn't a tile for an element - but an eye-catching device to gab your attention. 

Warning: if you don't want to know, stop reading now!

The Answers!


The 2000+ is a reference to one of the many year numbering systems that are in use around the world. In the Gregorian Calendar, the current year is 2020, the 20th year of the 21st century. So the 2000 is a hint, and the 20.167 is 20 years, plus .167 of a year, which is meant to be the elapsed part of the year to the beginning of March when Nullcon Goa 2020 started. The 1st of March is day 54 out of 365, which is 0.147, so Nullcon obviously started after that... Day 61 is the 8th of March, which is the day after the last day of the conference. Nullconium thus appears to have the unusual property that the mass number of its most stable isotope increases over the course of a year, then resets, increments and continues to rise: two concatenated sawtooth waveforms...

The green holes/circles allow a 20-sided regular icosagon to be drawn, which is unlikely to be very useful in most security-related areas, but it is interesting that it is another occurrence of '20'... This also highlights an interesting security consideration: The green layer has been interpreted by the badge manufacturer as the 'holes/drill layer' and so they have cut or drilled holes at those points (and probably wondered why I didn't put targets instead of circles! But I forgot this, and so added the screen '+' sign to the middle hole as a extra clue (as it says in the diagram above). I should have moved the green cross to another layer so that it got laser-etched and would be visible...

Of course, a security-minded person quickly realises that this is a classic potential vulnerability - the designer made a mistake that is subtle and hard to spot, but which may have consequences that the designer wasn't anticipating. In my case, a clue was missing and the diagram above highlights this! This type of vulnerability is not restricted to DXF files, of course: any place where two things are affected when only one was supposed to be, or when the coder assumes that two things are related when they shouldn't be, crops up in all sorts of coding situations. A bug like this is very hard to spot because people are very good at seeing patterns and associating things as groups - and in this case, this is exactly wrong - the hole and the '+' symbol should definitely be on two different layers. For a security analyst, this gives a clue to how to find this type of potential vulnerability: look for things that are out of context, exceptions or variations, or where multiple similar things happen at once - you can almost guarantee that a copy/paste/modify will have been done wrong, or that one or more references or paths or pointers will be wrong. people are very good at king this type of mistake, and very bad at spotting their mistake. Hiding in plain sight!

On the lowest edge of the badge are what look like books on a book-shelf, with some them falling over. You either see it immediately, or else you suddenly can see it when it is pointed out to you - a binary visual interpretation. once seen, you can't un-see it! These spell 'Nullcon' in a rather arcane way, but serve as a clue to some of the other numbers around the edge... I always try to include hints and pointers to things to get people started...

Having said this about leaving clues: the two holes for the lanyard do not have any significance (and 'lanyard-puzzles' are another related class of meta-puzzle!). This is probably the most difficult challenge on the badge. As in many security-related investigations, the hardest problem to solve is one that is not a problem with an answer!

The 'book-shelf' clue leads nicely into the data around the top edges. From the left, clockwise, these get gradually more difficult. CLLNNOU is just the letters in 'Nullcon' sorted alphabetically, which leads to 3522143, which is just the alphabetical positions in CLLNNOU (1223345) undone by forming NULLCON (3522143) and then reversing the order. Over on the right hand side, the 1876^2 + 2767 gives a result of 3,522,143, which is the non-reversed order of the letters of a sorted Nullcon. 
The long row of two digit numbers at the top of the badge is just Nullcon 2020 in 'ASCII', but using character 00 with its meaning of 'Null' instead of spelling out 'NULL' as 78,  85, 76, 76. So not quite normal ASCII... But the inclusion of 2020 is also a clue for the other two sets of numbers. 04 08 04 00 is meant to look like ASCII, but is actually a number: 4,080,400, which is 2020^2, and 4080400 is the same 2020^2 again, but this time shown without commas. At this point, you are probably thinking that 'Nullcon' and '2020' seem to be the answers to the challenges, but this is not true for all of the challenges... 


Underneath the 'tile', there are four rows of numbers and symbols. In general, the numbers are numbers, whilst the symbols are used to indicate the number base that has been used to express the number. So the top left number of 3744 is to the left of an octagon, and turns out to be 2020 in octal (base 8), even with a typo in the diagram! (The missing '4' - which is not missing for any reason other than a typo!) The 011 111 100 100 to the right is also in octal, but binary octal (which is octal expressed in binary form!): '011' is 3, '111' is 7, etc. 

The next row has what looks like binary again, because it is! The '\' symbol indicates binary just as the octagon indicates base 8. I did consider using Unary (base 1), where no symbol at all indicates zero, a single 1 represents 1, 11 is 2, 111 is 3, 1111 is 4, and so on, but decided that having 2020 1's in a row was going to be difficult to count! By using the '\' symbol as a clue that the base changes, the four pentagons indicate base 20, which is slightly outside most people's experience. Anyway, 510 is 2020 in base 20, which looks like there's some interesting patterning going on, and I'm sure that Numberphile et al on YouTube have covered this... (I'm reasonably sure, but didn't search too hard for it...) 

The next row down has base 5, base 18 (well outside my usual path!) and what looks like it might be an ethernet address... Well, it is, for the Tsinghua University in Beijing, China, but this is base 10: decimal, and those dots are shorthand for 'multiply'. So it means 101 x 5 x 2 x 2 = 2020. I'm very fond of giving you a repeated pattern and then suddenly jumping to something entirely different. Lulling you into a false sense of security, as they say!

Now that the context switch has happened, the final row is in base 10 (decimal), then hex (base 16) and then hex again. 45^2 - 5 = 2020, which is interesting, and 7E4 does look like hex, but it's just a straight conversion from 2020. D^2 - B1 is just hex arithmetic to try and test your agility.  

At this point, you might think you were finished. But there is one final puzzle - the numbers on the right hand side...


26, 20, 9 and 0 aren't ASCII, and they don't seem to be 2020 in any base. So what are they? If you replace the values in the rows with the number bases that are used, then you just get a grid of numbers. But if you add them up (clue is the + in front of the numbers on the right) then you get a very special number: 42. (42 is special in lots of ways !) I didn't use the Catalan 5-significance of 42 in this meta-puzzle - that would be for a maths conference, not a security conference...

Finally, after all of those 'Nullcon's and '2020's, we get to a different special number: '42'. Yay!

(It would have been boring if that was a 2020 as well, wouldn't it? Of course, 48.0952381..... x 42 is 2020, but that's another story.)

I hope you found the 42. If not, you now know how to find it!

And a summary!


---

More...


To find the first part of this post on the Nullcon badge, visit this page...

If you want more depth about one of the challenges above, then please visit this page...

---

I would like to thank the wonderful people at Payatu Technologies, who organise Nullcon, for great conferences (hardware.io, for example), and for asking me to do this badge design for Nullcon Goa 2020. 

---

If you find my writing helpful, informative or entertaining, then please consider visiting this link for my Synthesizerwriter alias (I write several blogs, and it makes sense to only have one donation page!):


Sunday, 1 March 2020

Nullcon 2020 Conference Badge

One of my many sidelines is creating meta-puzzles, as popularised by Cliff Johnson back in the 1980s. If you have never immersed yourself in an experience like The Fool's Errand, then meta puzzles are hard to describe. Suffice it to say that myself and a colleague spent far too much time trying to solve the inter-related puzzles contained inside.

Since then, I've done my own homages to Cliff in the form of 'Wall Games'. These are puzzles on pieces of A4 paper: blu-tacked to the wall at Christmas parties, conferences like hardware.io, the waiting areas for escape rooms, and various other places. Sometimes the puzzles are hard (some of the hardwear.io wall game puzzles required writing code to solve them!) and sometimes they are easy, and I try to not repeat the same idea twice. But the key concept is that everything is interlinked.


The Nullcon 2020 conference badge is another variation on the same idea. There are a number of hidden references on the badge, and your task is to decode them. Nothing on the badge is there by accident - everything has a meaning. Some of the puzzles are numerical, some are word-related, some are conceptual, and some are graphical. The only clues that you get are the badge, and the conference title.

Oh yes, and I have always loved the way that transparent green and orange plastic looks when laser-printed! For an even more amazing 'spirit level' experience, try putting fluorescein in water...

After the conference has finished, I will post the answers here on this blog, in case you missed the reveal at the conference...

---

I also publish a couple of other blogs. One of them is devoted to detailed technical explorations of hi-tech electronic music. Sometimes it does stray onto other topics - like a very popular post that reveals how to store text on Dropbox using zero bytes from your storage allocation...

---

The title of this blog is a kind of meta puzzle as well. There's a very easy way to remember how to spell it...

---

And the answers to the badge challenges? They are here...

---


If you find my writing helpful, informative or entertaining, then please consider visiting this link:


NULLCON 12, Berlin, April 2022

Here's the badge that I designed for the NULLCON 2022 Berlin security conference (and highly recommended training!).  The NULLCON 2022 b...